01 / UNDERSTAND
Content & human context
Assessing nuance in content, creator fit and audiences — not just numeric performance.
I'm Amelia Ph. Nguyen — a Business Administration student and early-career operator working across creator operations, commerce and analytics. I care about making complex work clearer, more useful and easier to trust.
My path into AI didn’t begin in a lab. It began in real-world operations: supporting product launches, reviewing creator content, analyzing customer data and building tools that made everyday work easier.
Across very different teams, I kept coming back to the same question: how can we turn individual judgment into a reliable, repeatable process — without losing the human context?
Explore the journeyAssessing nuance in content, creator fit and audiences — not just numeric performance.
Separating what is observed from what is assumed, missing or needs validation.
Prototyping workflows that reduce repetition and make human review easier.
Four chapters, one evolving curiosity. Select a chapter to see what I worked on and what it taught me.
My first chapter brought me into digital commerce, creator partnerships and product launches. Co-leading TikTok Shop livestreams taught me to connect shopper insights to concrete decisions and measurable results.
Results from roles at INNO, 4AM and Mercedes-Benz Vietnam, presented separately from the SIGNAL prototype.
Professional experience metrics are separate from synthetic test results in the SIGNAL project.
Screening profiles, checking content guidelines and updating reports showed me how much work followed repeatable patterns. I began experimenting with AI-assisted workflows. Then a better question emerged: if a system makes a decision faster, how do we know when it is wrong?
See what that question became ↗Inspired by a question from everyday operations: when automation makes a judgment, how can we check its evidence and improve the next decision?

An evidence-first evaluation workflow combining creator and content inputs, rule-based rubrics, optional AI text assessment, human review and rubric comparisons.
The five-case exercise illustrates rubric revision, not real-world model accuracy or proof of generalization.
Enter the SIGNAL case study ↗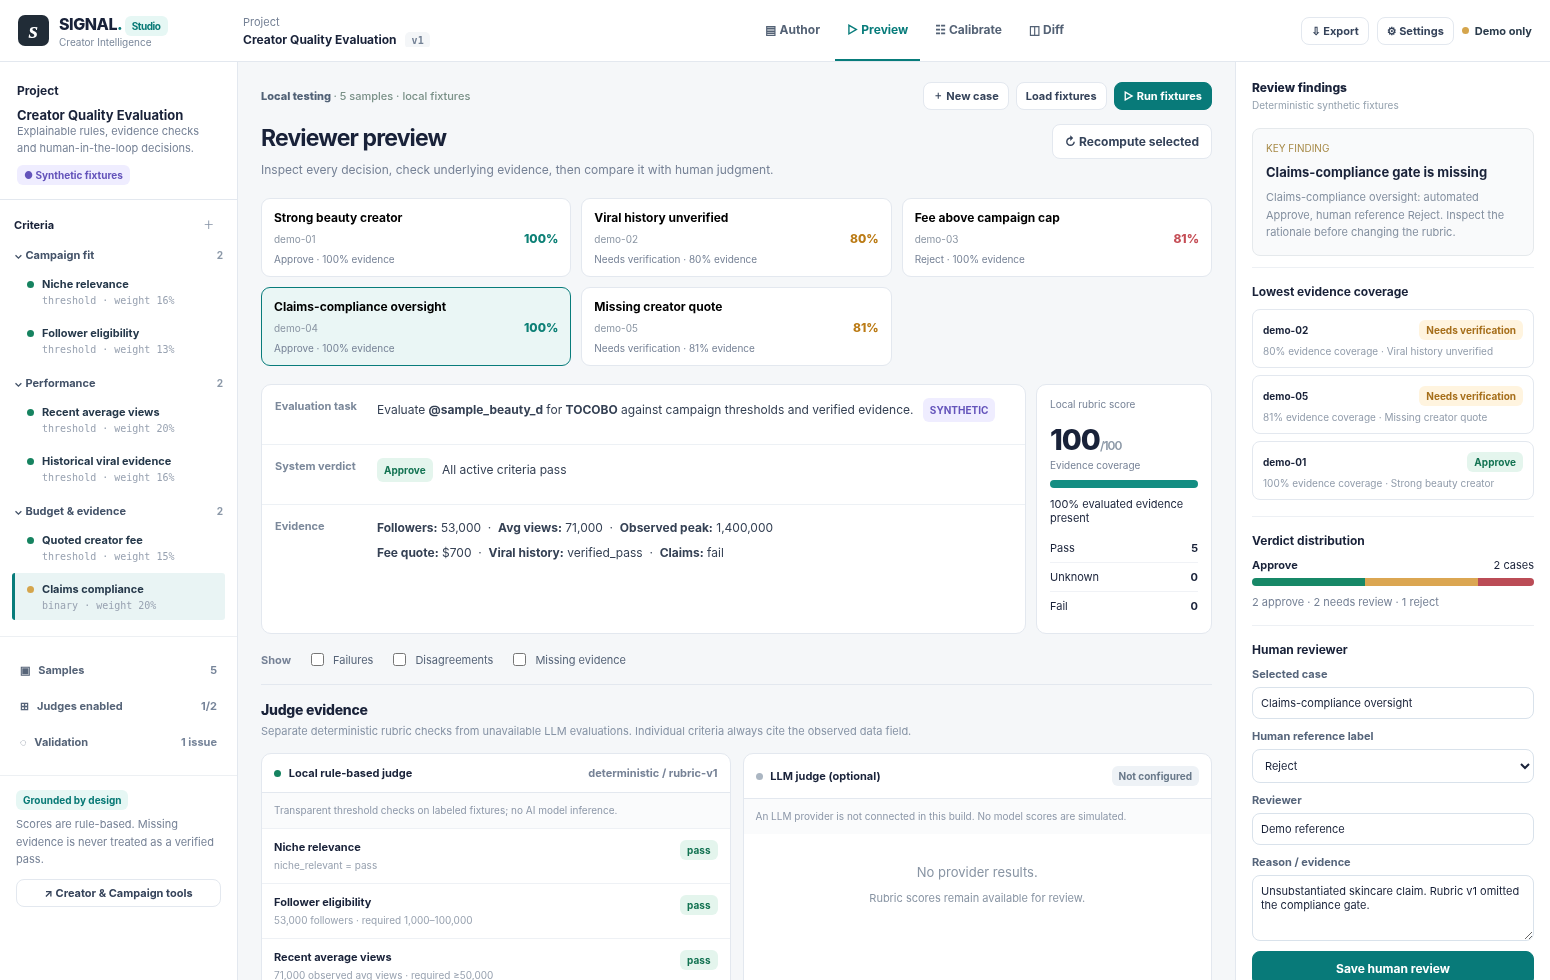 ACTUAL PROTOTYPE SCREENSHOT
I'm interested in thoughtful technology, operations, data quality and the human decisions behind reliable systems. Happy to connect or exchange ideas.